AI.M.E. (Agentic AI Maturity Evaluation)
AI.M.E. is a multi-agent research system that scores how organisations adopt and govern AI using public evidence. I lead the programme at Braidr, covering the evaluation framework, research design and technical delivery. Two cohort studies are published, the FTSE AIM 100 (September 2025) and the FTSE 350 (July 2026), and the system now runs on demand as a production research service.
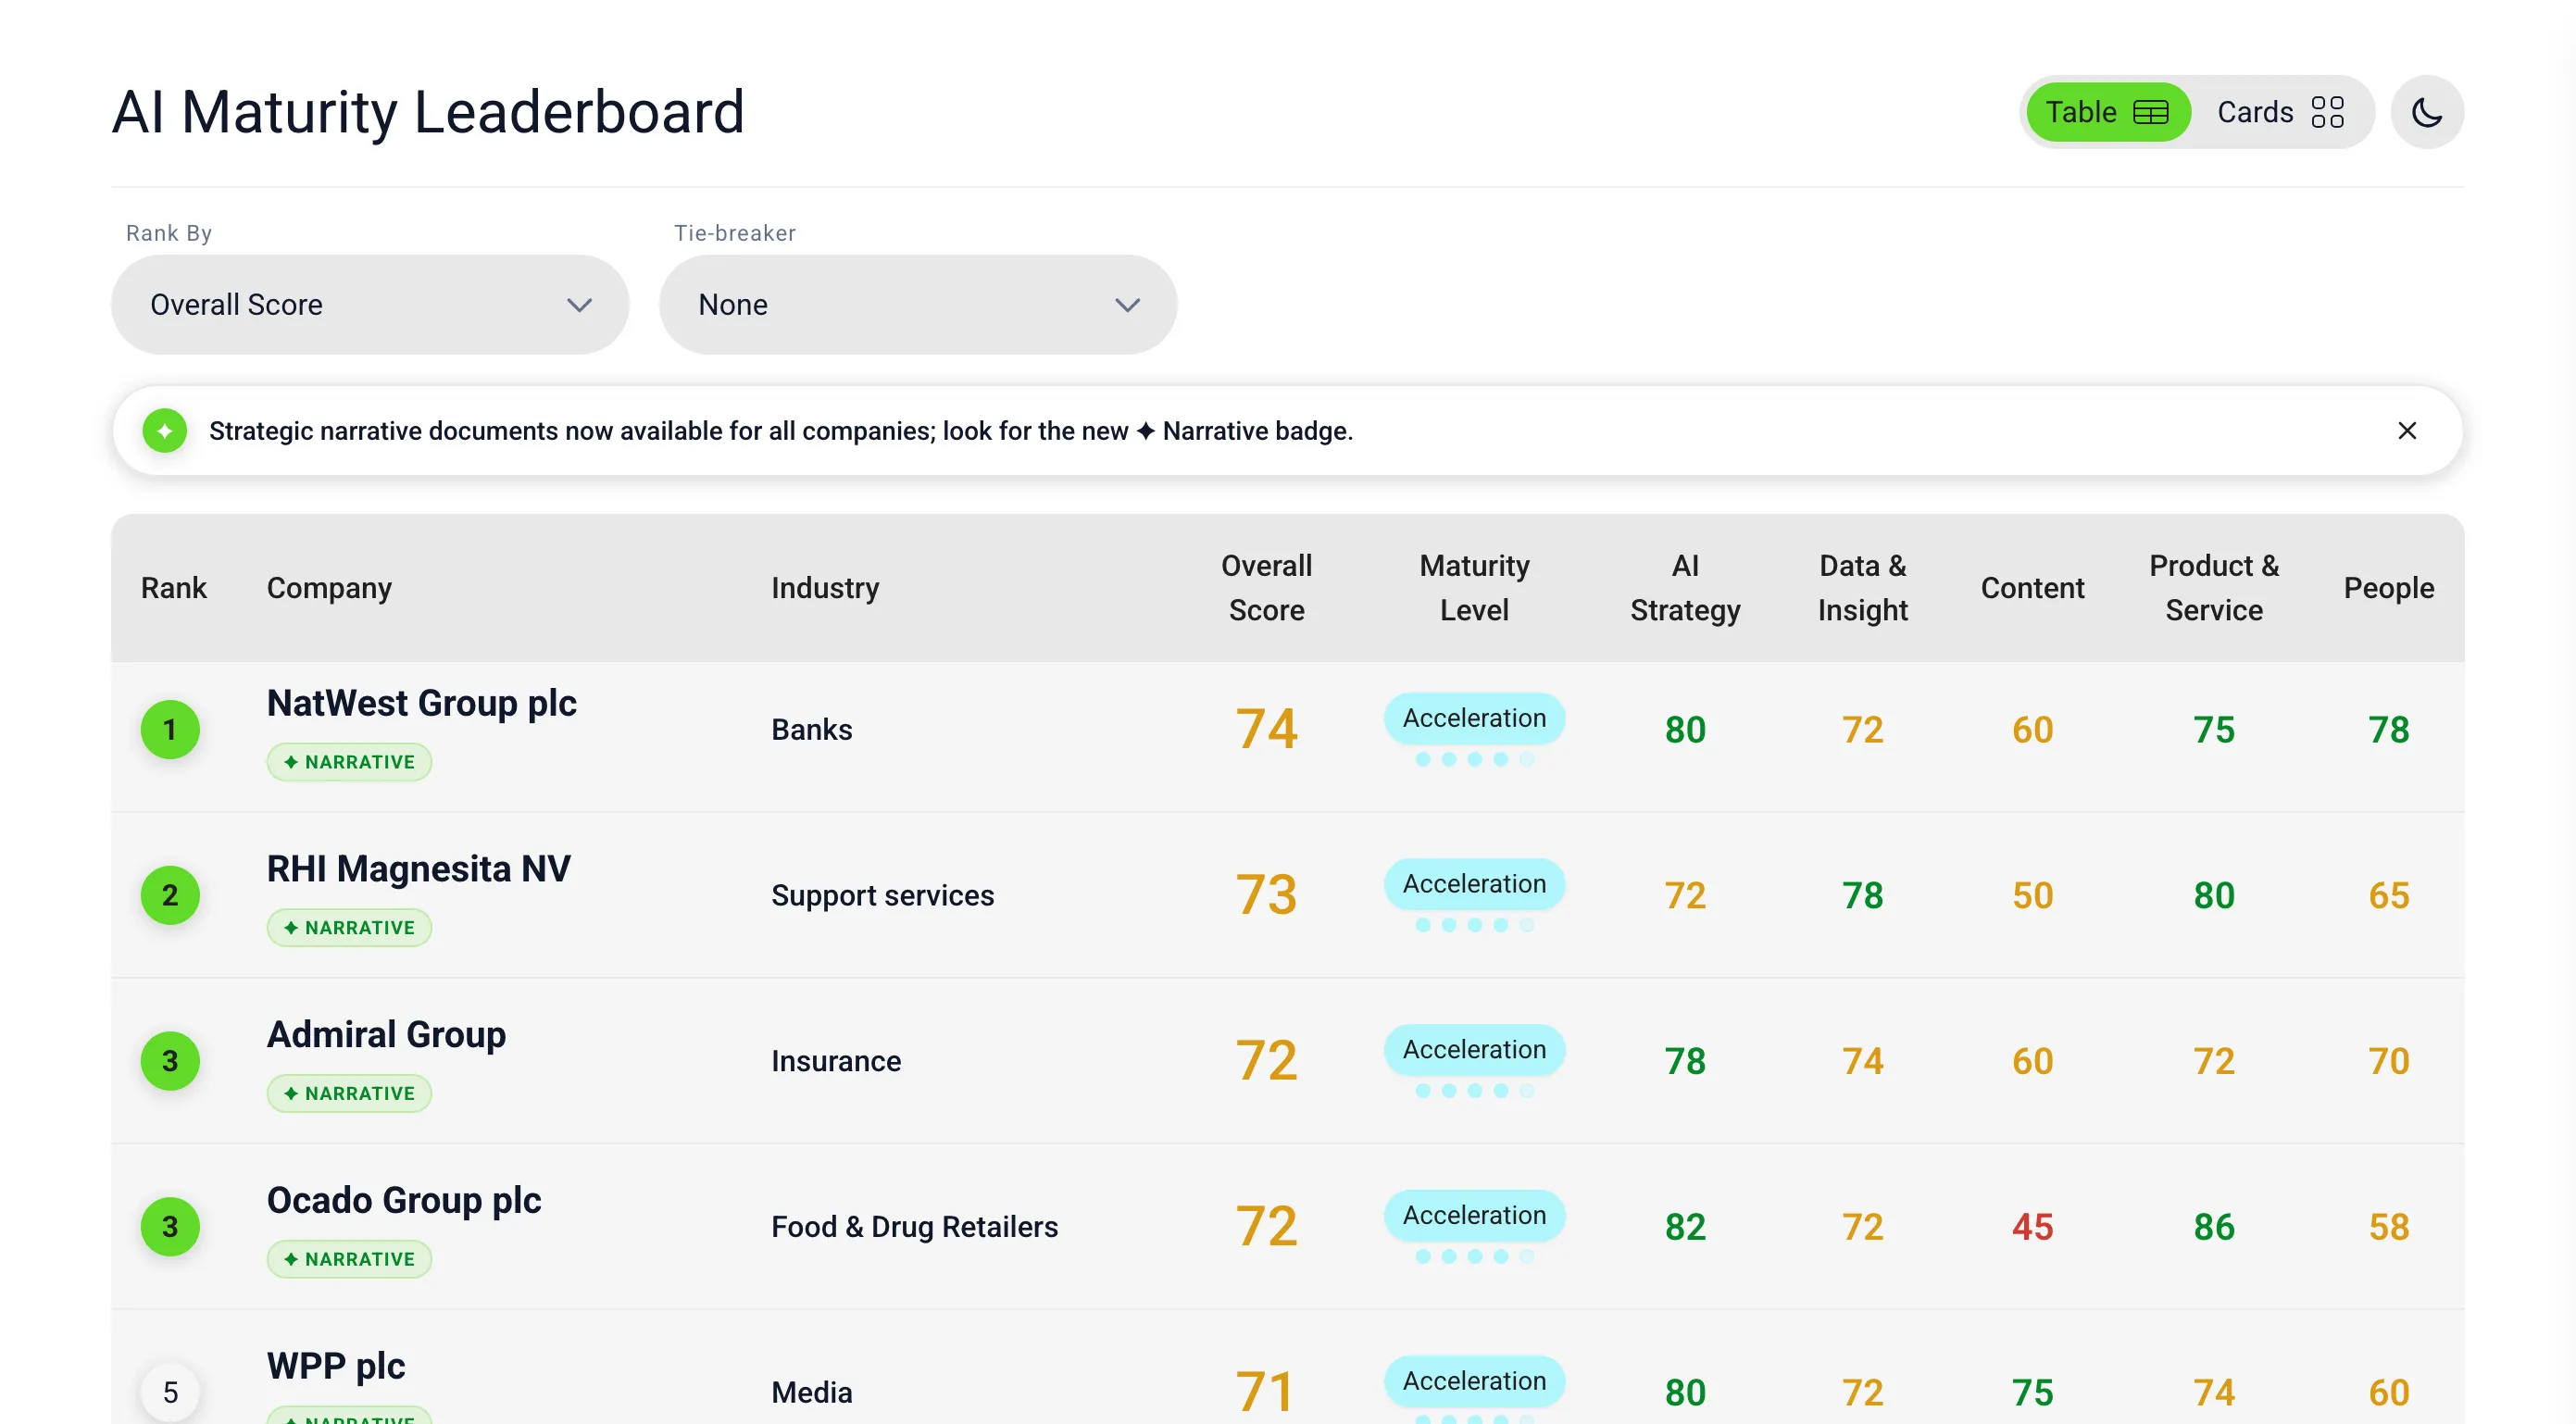
My role and the team
I was the lead architect and engineer. I also did the analysis, produced the findings and presented them internally and externally. My engineering team comprised one machine learning engineer and one data engineer. I worked with a strategist, the Chief AI Officer and our internal web development team.
Working from public evidence
A company’s public record gives us evidence about its AI capability, but no direct view of its internal practice. I made that limit part of the design from the start. Every finding cites an identifiable source, and the report flags uncertainty or thin evidence. Scores have to be explainable from those sources. The model can still misread them; reporting is restricted to the evidence it was given. That limits the assessment to publicly evidenced maturity.
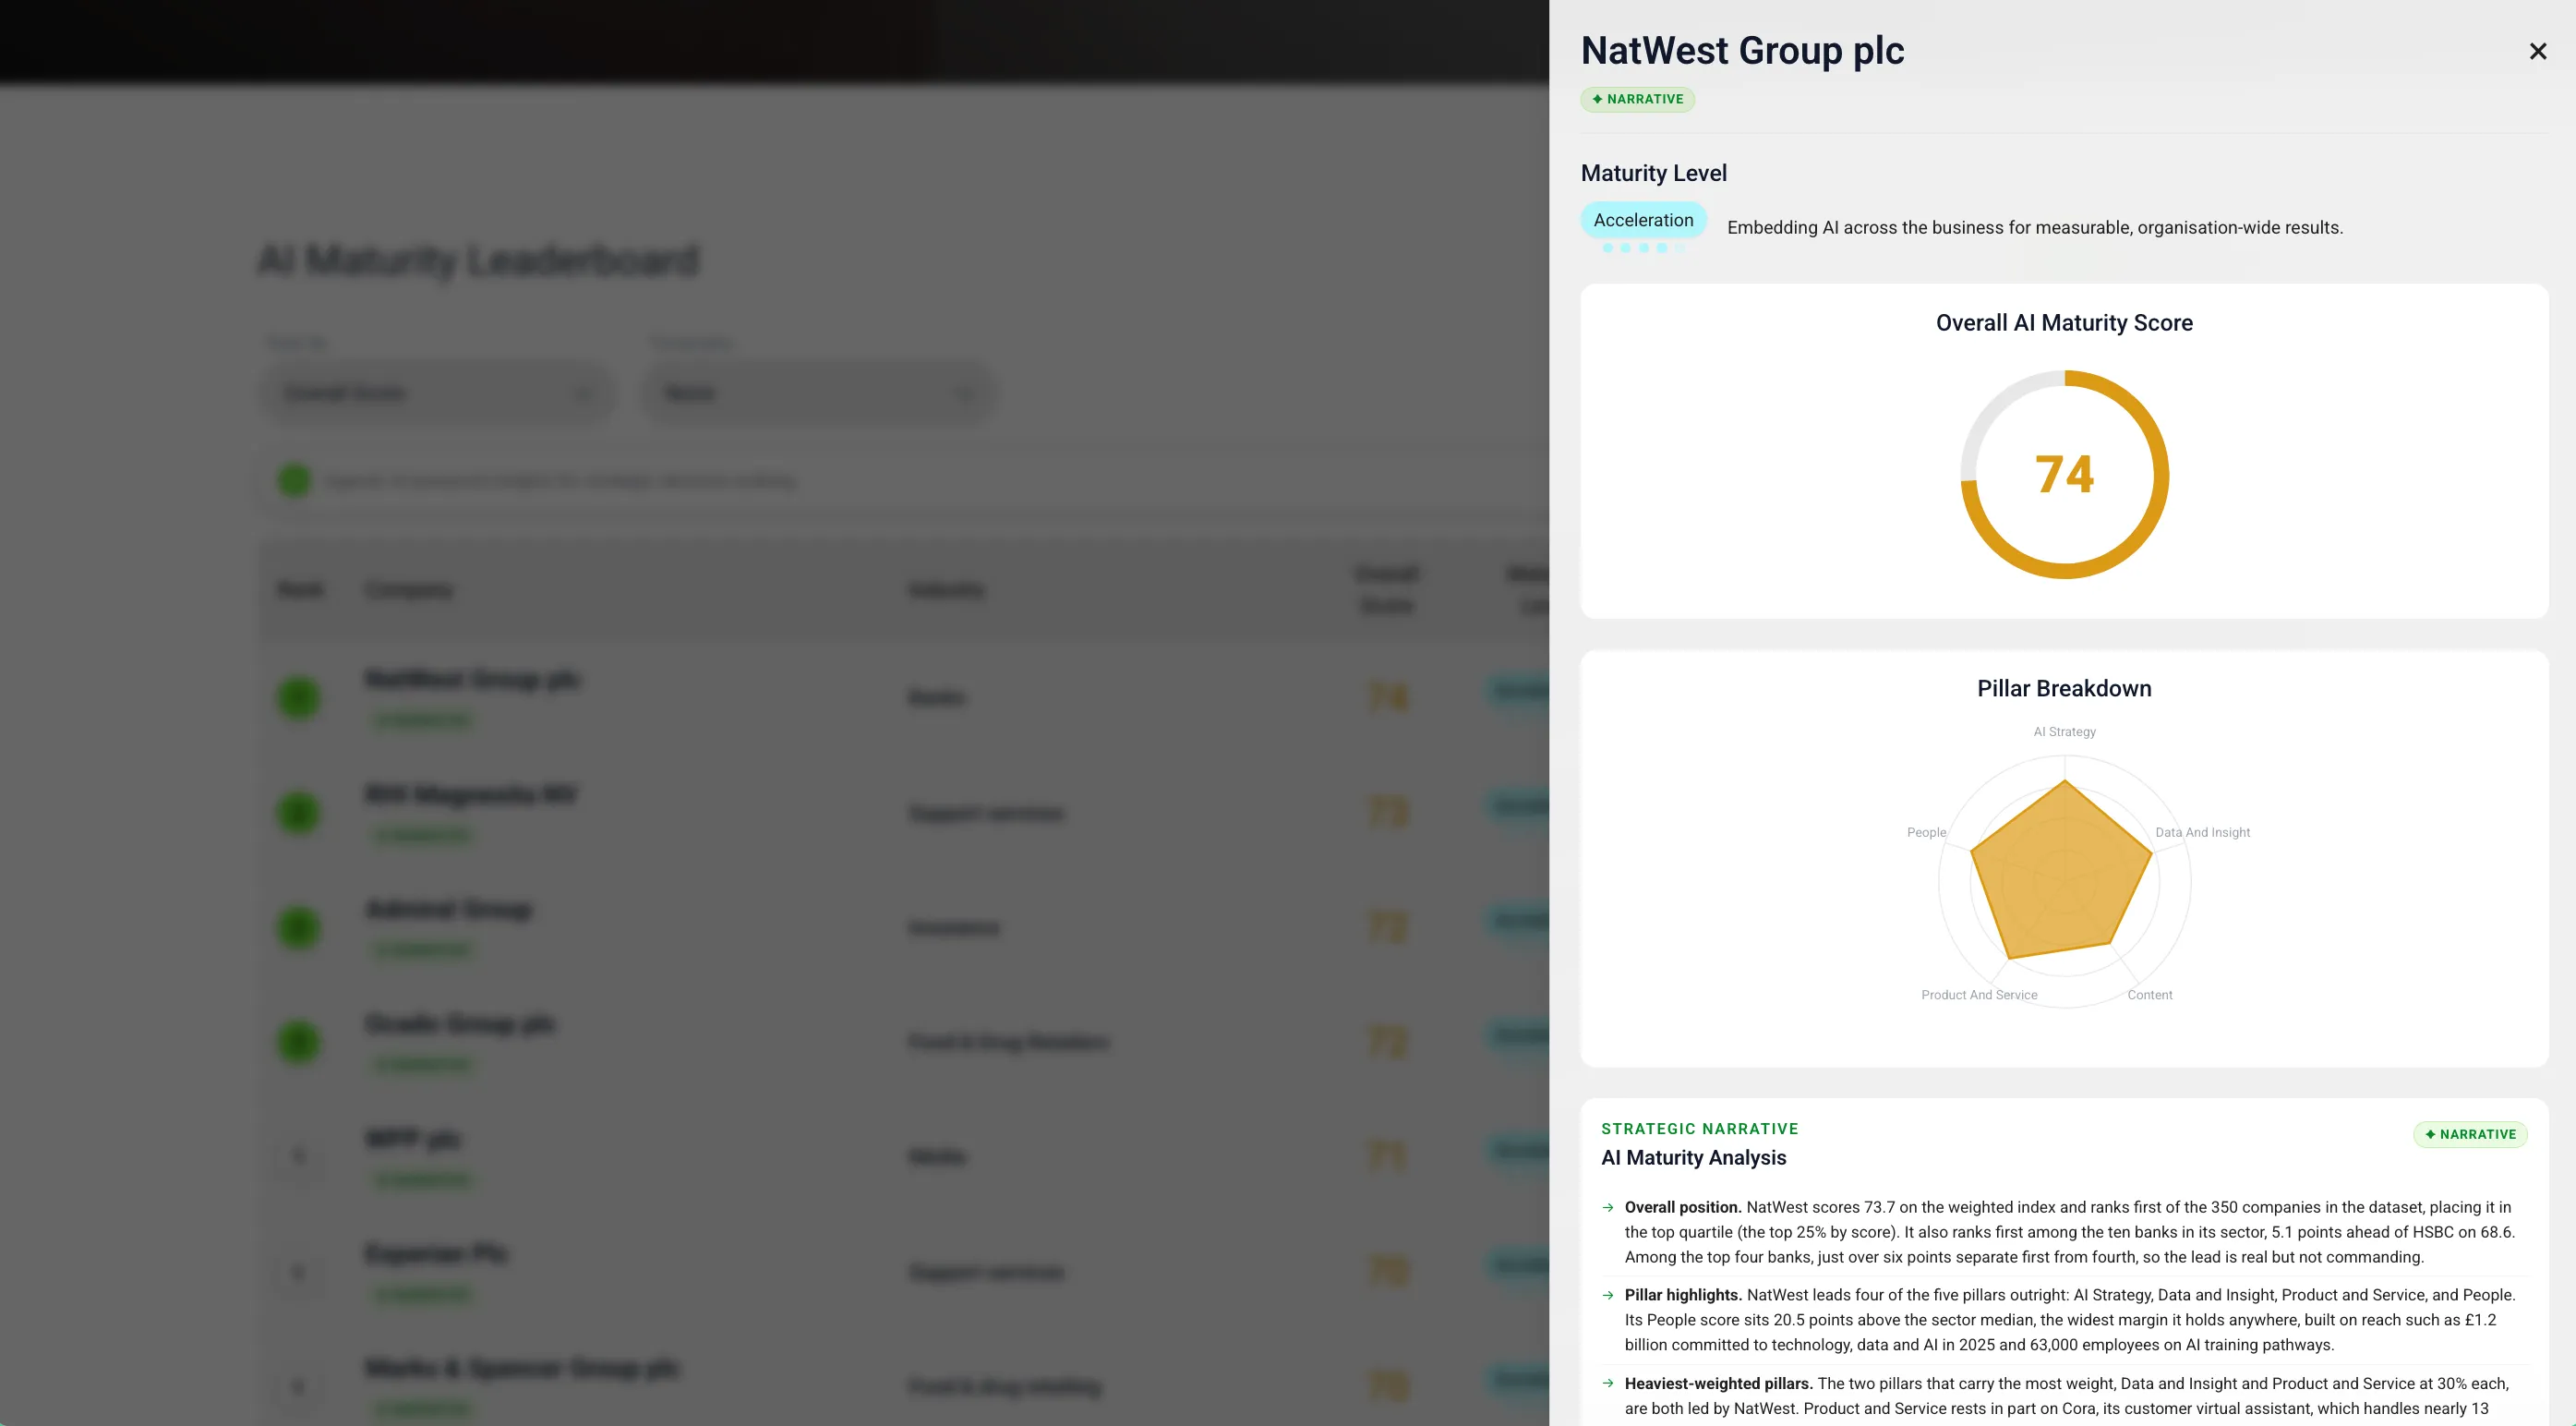
I defined what the assessment measures: five pillars (AI Strategy, Data & Insight, Content, Product & Service, People), a maturity curve running from Analogue to Augmentation, and the 180+ criteria the assessors reason against. I also chose to publish the methodology in full, so anyone can argue with the scores on their workings rather than taking them on trust.
How it works
The system runs on Google’s Agent Development Kit (ADK). A research coordinator delegates to pillar specialists, and the specialists share an intelligence bus, so a finding that surfaces under Data & Insight can do useful work under AI Strategy too. Then comes the assessor council, organised by maturity stage rather than topic. Each assessor specialises in the signals that separate genuine adoption from a well-funded pilot, and the council debates the evidence over structured rounds until it reaches consensus. Findings pass through multiple layers of fact-checking agents before reporting.
The models gather and weigh evidence, but final scores are calculated deterministically in code, so the same inputs give the same figures on every run. The models argue; the code keeps score. Reports contain only cited findings, each with a source and a reliability rating, so readers can judge which findings to rely on.
Human review and regression checks
We used human-in-the-loop evaluation alongside deterministic checks against figures we could calculate directly.
The strategic reporting agents went through 12 rounds of editorial feedback. Each round included regression analysis of outputs from a representative 10% sample of the dataset, so we could track how quality changed as we revised the agents.
We built QA agents to flag inconsistencies, contradictions, tone problems and claims that went beyond the evidence. We used the flags to track problems across revisions and guide human review and corrections.
Published studies and open questions
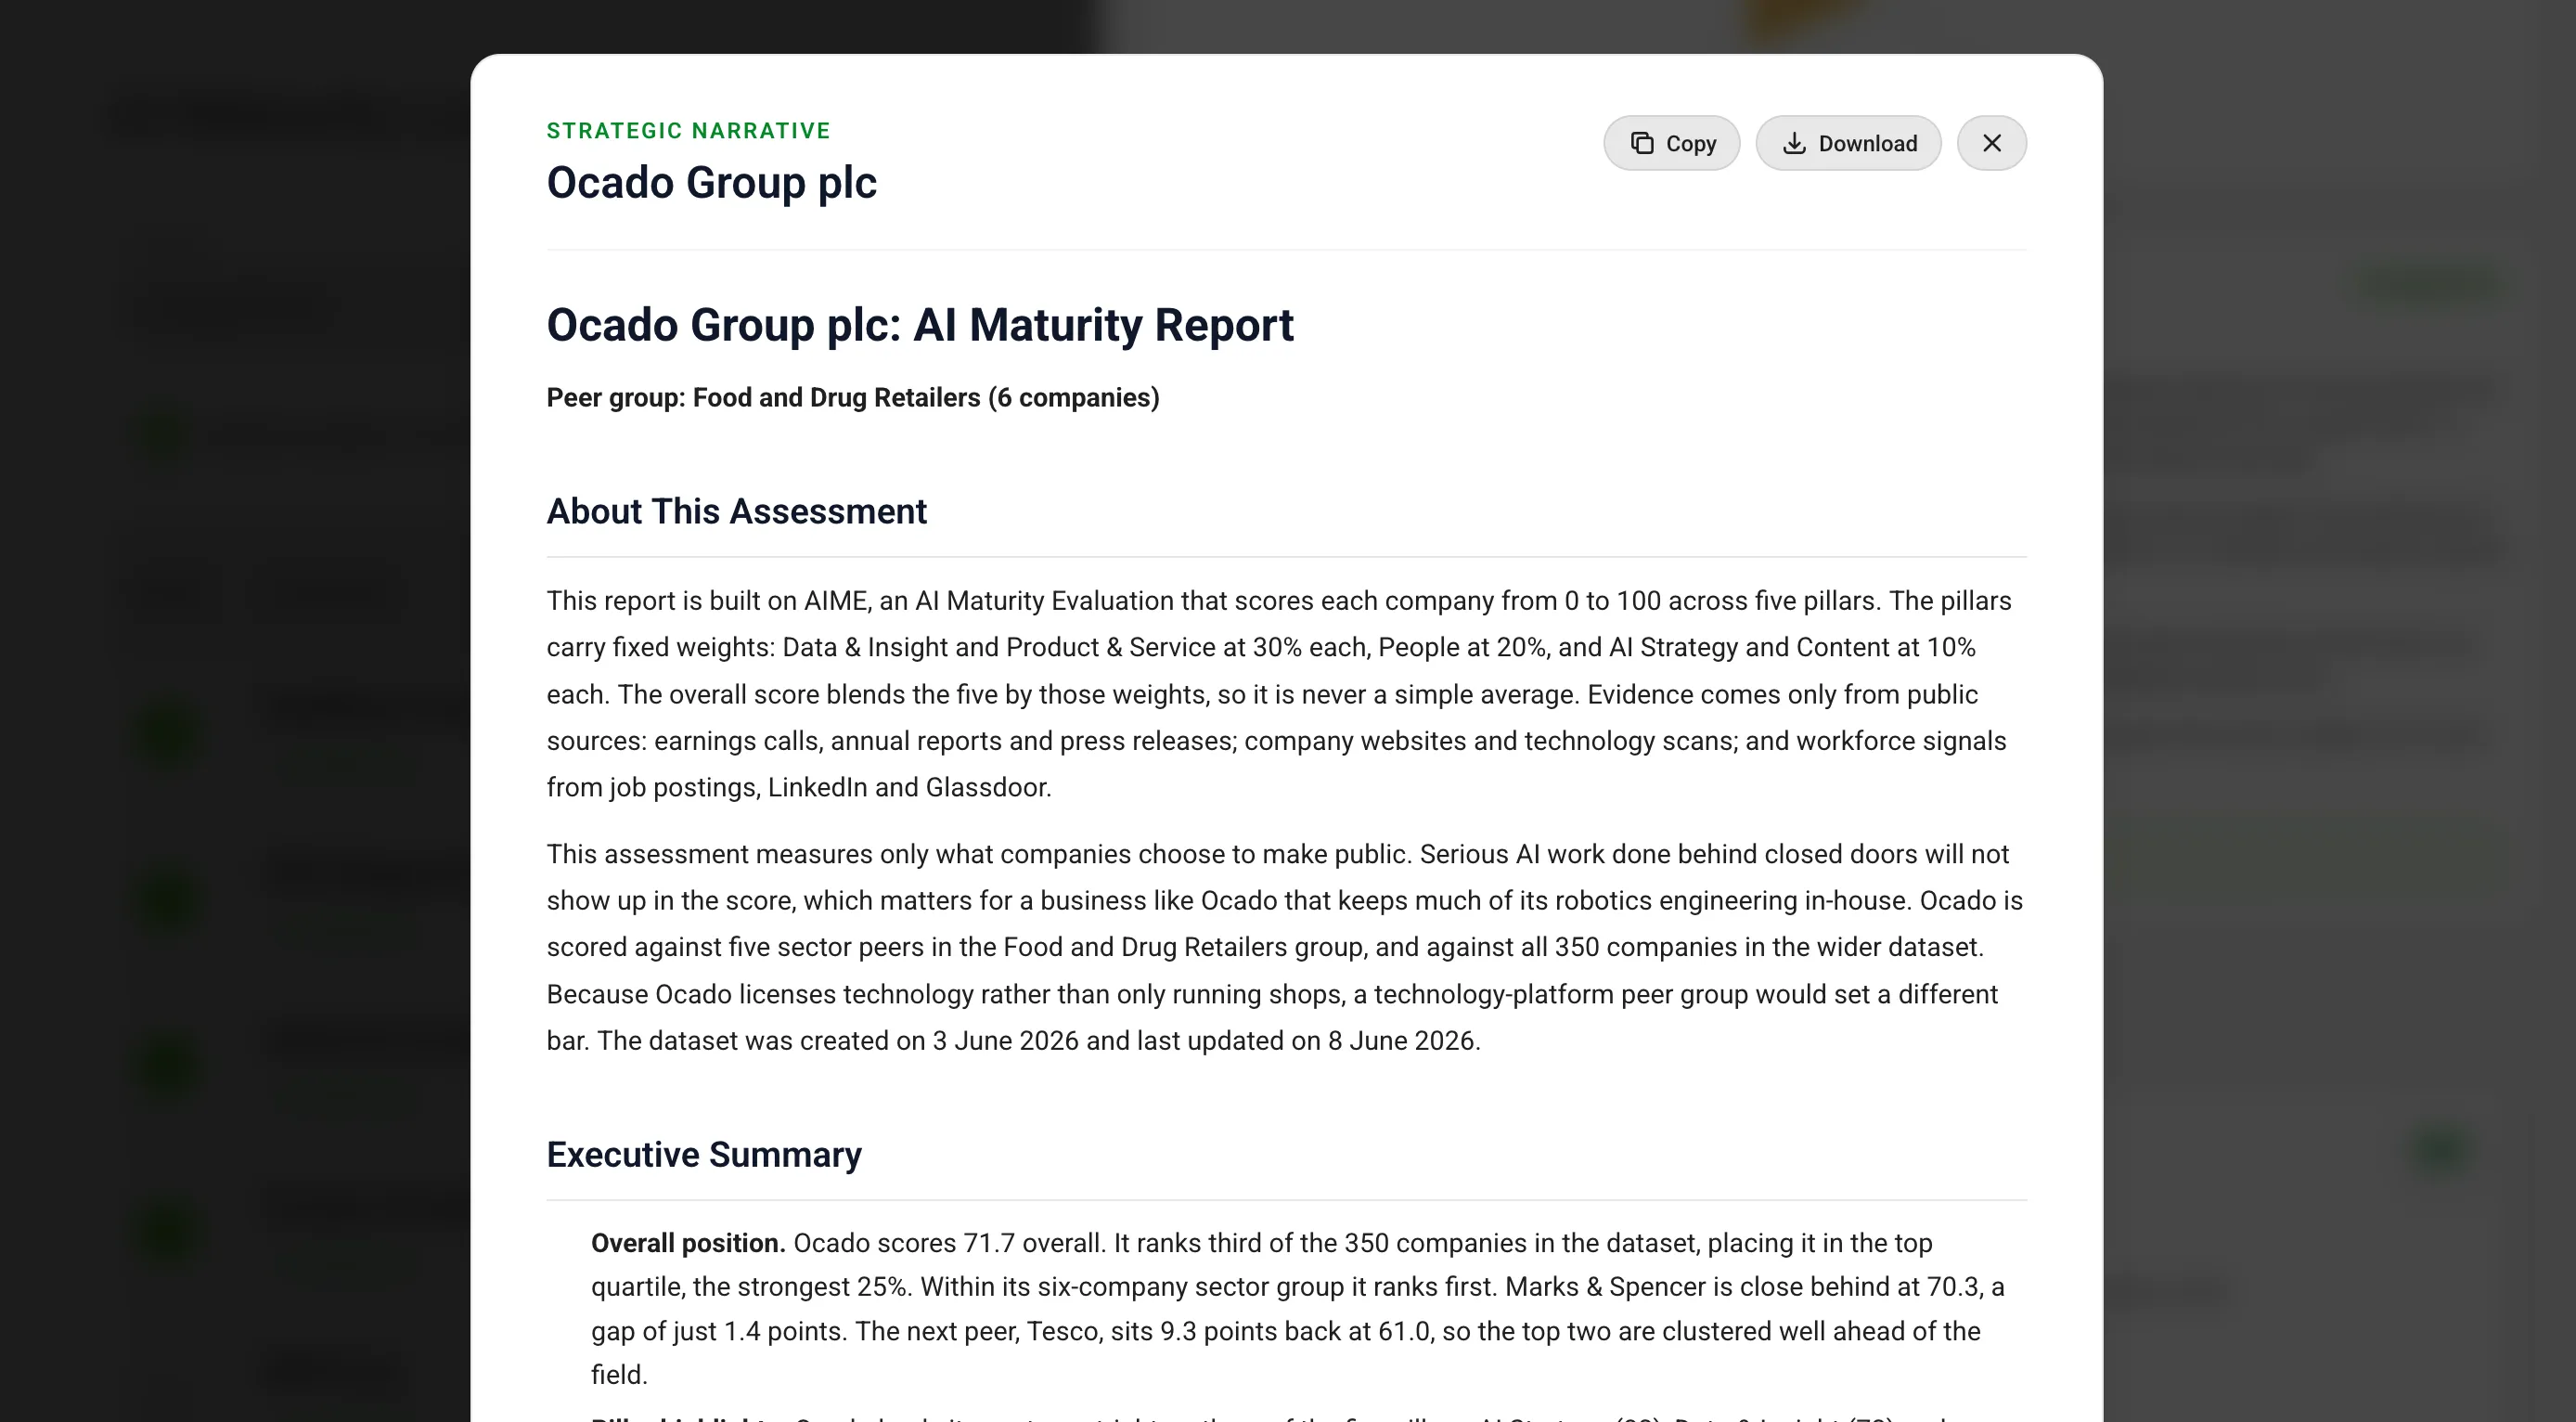
The FTSE AIM 100 run assessed 100 companies in about two weeks, at roughly $1 to $2 per company. The FTSE 350 study took 350 companies through just under 99 hours of runtime, drawing on 5,878 distinct public sources. Sixty-five percent of its evidence findings came out rated four or five out of five for reliability, per the published methodology. I’m pleased with that, though the ratings depend on the fact-checkers’ judgement.
One open question concerns subsidiaries. Several FTSE 350 constituents are listed parents sitting above dozens or hundreds of consumer brands, and it’s not obvious that a parent’s score carries down to them. I’ve designed an empirical test that compares the brands’ own evidence rather than assuming the score transfers. The assessors are also models, and models change when their makers update them. Keeping assessor behaviour consistent across provider updates remains an ongoing evaluation concern.